Articles
Guides and field notes on OpenTelemetry, Kubernetes observability, and cost management, from the team building Randoli.
Featured
Observability
Data Sovereignty in the Age of Autonomous Observability
Building an autonomous SRE Agent taught us that more context produces better root-cause analysis. Rather than centralizing more telemetry, the answer is to move intelligence closer to where the data lives.

Rajith Attapattu
Sep 27, 2026
Cost Management
Guide to Kubernetes Cost Management - Part 3
In the final part of this series, we move from optimizing individual workloads to building a repeatable FinOps practice: the Crawl, Walk, Run maturity model applied to Kubernetes, why recommendations alone don't scale, and how SRE Agents can help close the loop between detecting an inefficiency and safely acting on it.
Rajith Attapattu
Sep 5, 2026
Cost Management
Guide to Kubernetes Cost Management - Part 2
In this second part of the series, we move from understanding Kubernetes cost to actually optimizing it: attributing spend to workloads, establishing a baseline, rightsizing without guesswork, optimizing the cluster underneath, and closing the loop with continuous validation and automation.
Rajith Attapattu
Aug 15, 2026
Cost Management
Guide to Kubernetes Cost Management - Part 1
In this first part of a three-part blog series, we will explore the fundamentals of Kubernetes cost management, breaking down the factors that contribute to Kubernetes cost and the challenges organizations face in controlling them. Understanding these challenges is the first step toward building a cost-efficient and scalable Kubernetes environment.
Rajith Attapattu
Jan 22, 2026
All articles
Observability
Data Sovereignty in the Age of Autonomous Observability
Building an autonomous SRE Agent taught us that more context produces better root-cause analysis. Rather than centralizing more telemetry, the answer is to move intelligence closer to where the data lives.
Rajith Attapattu
Sep 27, 2026
Cost Management
Guide to Kubernetes Cost Management - Part 3
In the final part of this series, we move from optimizing individual workloads to building a repeatable FinOps practice: the Crawl, Walk, Run maturity model applied to Kubernetes, why recommendations alone don't scale, and how SRE Agents can help close the loop between detecting an inefficiency and safely acting on it.
Rajith Attapattu
Sep 5, 2026
Cost Management
Guide to Kubernetes Cost Management - Part 2
In this second part of the series, we move from understanding Kubernetes cost to actually optimizing it: attributing spend to workloads, establishing a baseline, rightsizing without guesswork, optimizing the cluster underneath, and closing the loop with continuous validation and automation.
Rajith Attapattu
Aug 15, 2026
Log Monitoring
How to Monitor Logs in Production
This post covers four operational gaps that make log monitoring hard in production: fragmented log querying across services, missing correlation between logs and traces, the inability to see logs in the context of your broader APM signals, and the failure to detect recurring error patterns before they escalate. We walk through each gap and show how treating logs as a first-class part of your investigation workflow: queryable, correlated, and continuously monitored, changes how fast you get to root cause.

Kunal Verma
Apr 27, 2026
Guide
Monitoring Kafka at Scale with OpenTelemetry
In this post, we'll walk through what production-grade Kafka observability actually looks like: which metrics matter and why, where traditional monitoring falls short, and how an OpenTelemetry-native approach gives you the correlation and visibility you need to catch these problems before they become incidents.
Kunal Verma
Apr 27, 2026
Observability
Monitoring RED Metrics in Production
RED metrics — Rate, Errors, and Duration — give you direct visibility into what your users are actually experiencing, something infrastructure metrics like CPU and memory can't tell you on their own. This post covers what each signal means, how to interpret changes in rate, error rate, and percentile-based latency, how to collect RED metrics using OpenTelemetry's spanmetrics connector, how to use them as the foundation for SLO monitoring, and how to turn that visibility into active alerting so you know about problems before your users do.
Kunal Verma
Apr 27, 2026
Observability
Best Practices for Log Monitoring in Production
What good log monitoring looks like in practice: how it differs from traditional logging, how to capture the right data, and the principles that keep logs useful in production.

Isha Bhardwaj
Feb 12, 2026
Cost Management
How to Make GenAI Costs Observable in Production
In this blog, we’ll walk through a set of practical strategies teams use in production to regain control over GenAI spend by treating cost as an operational signal, designing the right telemetry, and closing the feedback loop between engineering and finance before the next spike shows up on a bill.
Kunal Verma
Feb 10, 2026
Cost Management
5 Reasons GenAI Costs Become Unpredictable in Production
Five reasons GenAI costs become unpredictable in production, and why traditional infrastructure and APM metrics can't explain a bill spike that traffic alone doesn't.
Kunal Verma
Feb 4, 2026
Observability
Log Monitoring at Scale: Why It Breaks in Production
Why log monitoring breaks down at scale, and the top five production-grade logging problems teams repeatedly face, illustrated with real-world distributed-systems scenarios.
Isha Bhardwaj
Feb 4, 2026
Cost Management
Guide to Kubernetes Cost Management - Part 1
In this first part of a three-part blog series, we will explore the fundamentals of Kubernetes cost management, breaking down the factors that contribute to Kubernetes cost and the challenges organizations face in controlling them. Understanding these challenges is the first step toward building a cost-efficient and scalable Kubernetes environment.
Rajith Attapattu
Jan 22, 2026
Observability
How to Monitor Go Applications with OpenTelemetry
How to instrument Go applications with OpenTelemetry to catch tail-latency spikes, goroutine leaks, and slow downstream calls across concurrent execution paths.
Isha Bhardwaj
Jan 20, 2026
Observability
Top Redis Metrics to Monitor in Production Scale Environments
This guide focuses on the Redis metrics that matter most for identifying instability, preventing performance degradation, and maintaining predictable behavior at scale.
Isha Bhardwaj
Jan 18, 2026
Observability
Monitoring Redis Metrics with OpenTelemetry
In this guide, we’ll look at how Redis can be monitored using OpenTelemetry, outline the core metrics that shape cache behavior, map the telemetry flow end-to-end, and walk through how to instrument Redis and visualize meaningful performance insights.
Isha Bhardwaj
Dec 15, 2025
Observability
Top MongoDB Metrics to Monitor in Runtime Environments
This guide focuses on the MongoDB metrics that most clearly signal emerging stress and operational risk, helping engineering teams maintain reliable performance and predictable cluster behavior at scale.
Isha Bhardwaj
Nov 24, 2025
Observability
Monitoring MongoDB Metrics with OpenTelemetry
In this guide, we’ll explore two approaches to monitoring MongoDB, discuss key considerations for each, break down the end-to-end telemetry flow, and walk through how to instrument your setup and visualize critical metrics effectively.
Isha Bhardwaj
Nov 21, 2025
Observability
Monitoring Kafka Metrics with OpenTelemetry
In this guide, we’ll explore the different approaches to monitor Kafka with OpenTelemetry, explain how each of the methods works, and provide guidance on selecting the right option for your use case.
Isha Bhardwaj
Nov 12, 2025
Observability
Monitoring PostgreSQL Metrics with OpenTelemetry
In this guide, we’ll walk through the two main approaches to monitoring Postgresql, comparing their trade-offs, break down the end-to-end data flow, and explore how to instrument your setup and visualize key metrics effectively.
Isha Bhardwaj
Nov 12, 2025
Observability
Top Kafka Metrics to Monitor in Production
The Kafka metrics that actually warn of downtime, data loss, or cascading failures in production, beyond just checking that the cluster is up and running.
Isha Bhardwaj
Nov 12, 2025
Observability
Top ProgreSQL Metrics to Monitor in Real Time
This guide dives into the most important PostgreSQL engine-level metrics that SRE and DevOps teams must track to ensure stability, performance, and reliability at scale.
Isha Bhardwaj
Nov 12, 2025
Guide
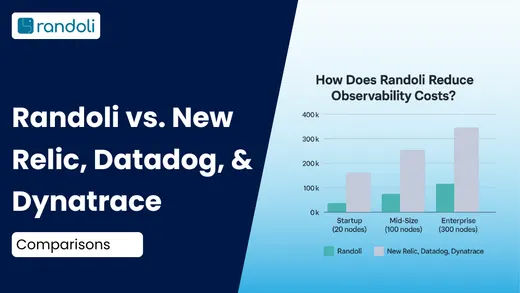
Breaking Down Observability Costs: Randoli vs. New Relic, Datadog, & Dynatrace
How observability costs for Kubernetes compare across Randoli, Datadog, New Relic, and Dynatrace at 50, 200, and 500 hosts, and why the gap comes from architecture: local processing means there is no ingestion meter to pay for.
Rajith Attapattu
Oct 6, 2025
OpenTelemetry
OpenTelemetry 101 - A Practical Guide to Unified Observability
This guide will walk you through how OpenTelemetry works, why it’s essential for modern engineering teams, and how to get started implementing it.
Kunal Verma
Oct 6, 2025
Logging
3 Challenges When Implementing Logging & How To Overcome Them
Logging is often seen as a simple building block — but done poorly, it becomes expensive noise that slows incident response and inflates infrastructure costs. This guide explores three critical logging challenges that plague development teams: excessive low-value logs, missing contextual identifiers, and fragmented monitoring views, plus actionable solutions to optimize your logging strategy.
Rajith Attapattu
Aug 28, 2025
Autoscaling
A Guide to Kubernetes VPA
In this article, we’ll explore how the Vertical Pod Autoscaler (VPA) helps solve these challenges by automatically optimizing resource allocation for Kubernetes workloads. We’ll cover its components, how it works, types of recommendations it provides, and the steps to set it up, along with real-world use cases and practical insights.
Kunal Verma
Aug 28, 2025
Security
Best Practices Analysis & CVE Scanning with KubeScape
An analysis of Kubescape, the open-source CNCF tool for scanning Kubernetes clusters for vulnerabilities, misconfigurations, and compliance issues, and how to use it well.

Sandaruwan Lakshitha
Aug 28, 2025
Cost Management
How to Measure Network Cost in Kubernetes
Network cost especially can be difficult to estimate properly with all of the complex factors that affect and determine how much you will be billed at the end of the month. The purpose of this article is to provide a comprehensive understanding of all of the different sources that make up your total network cost in Kubernetes and provide additional context for how it is calculated.

Rosa Lopes
Aug 28, 2025
Cost Optimization
Installing & Configuring OpenCost
A walkthrough of installing and configuring OpenCost to track Kubernetes cost increases and see what's driving them, before they show up as a surprise on the bill.

João Pimentel
Aug 28, 2025
Announcement
Introducing Randoli Observability and Cost Management
With direct feedback from users and a keen understanding of the diverse needs within modern cloud-native environments, we’re excited to announce a strategic split of our flagship platform into two focused solutions - Observability for Kubernetes and Cost Management for Kubernetes.
Rajith Attapattu
Aug 28, 2025
Kubernetes
OpenCost Compatibility Patch for Red Hat OpenShift
Why OpenCost broke on Red Hat OpenShift after a change to how the platform's managed Prometheus handles metric labels, and how Randoli built a patch to fix it.
Rosa Lopes
Aug 28, 2025
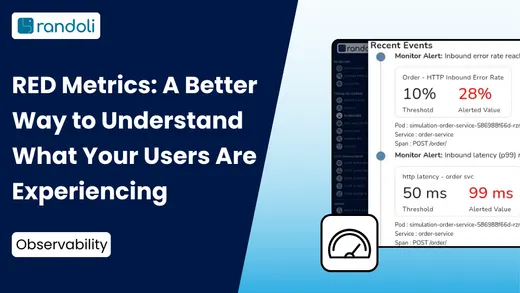
Observability
RED Metrics: A Better Way to Understand What Your Users Are Experiencing
When monitoring applications, most teams start with CPU and memory. These are easy to collect and visualize. But while they help you understand system resource usage, they often fail to tell you what really matters: 👉 What is the user experiencing? In this post, I’ll walk you through a better way to monitor services using RED metrics, and how they can help you move from system-centric to user-centric observability.
Rajith Attapattu
Aug 28, 2025
Observability
Reduce MTTR with Runbooks
How runbooks reduce Mean Time to Resolve by replacing scattered documentation and ad-hoc Slack messages with clear, accessible troubleshooting steps for Kubernetes incidents.
Kunal Verma
Aug 28, 2025
Right Sizing
Kubernetes Right Sizing: A Practical Guide to Rightsizing Workloads
A practical guide to Kubernetes right sizing (rightsizing): the fundamentals, the challenges teams face implementing it, and data-driven strategies for optimal resource allocation.
Kunal Verma
Aug 28, 2025
Right Sizing
VPA Recommendation Mode: A Practical Rightsizing Workflow
A mode-by-mode walkthrough of VPA recommendation mode, Off, Initial, Recreate, and InPlaceOrRecreate (Auto is now deprecated), so you can roll out Vertical Pod Autoscaler rightsizing in production without surprise pod restarts.

Abdul Ali
Aug 28, 2025
OpenCost
Running OpenCost on OpenShift
The goal of this article is to guide you through each of the installation steps to avoid the common issues that occur when OpenCost is installed on OpenShift without being correctly configured. Because of our work testing OpenCost on various different environments, we've gained a ton of experience debugging and resolving these provider-specific problems.
Rosa Lopes
Aug 28, 2025
Best Practices
5 Tips for Monitoring Kubernetes Spend
If you have any interest in reducing the cost of your Kubernetes cluster, here’s a quick, easy and free way to start: install OpenCost on your k8s cluster. After it’s been running for a couple of days, you’ll start seeing useful data! This article has 5 pro tips for making the most of your OpenCost installation and monitor your k8s spend
João Pimentel
Aug 28, 2025
No articles match your search. Try a different term or clear the topic filter.